

NVIDIA RTX PRO 6000 Blackwell and multi-GPU compute.
Accelerate AI training, inference and high-performance workloads with the NVIDIA RTX PRO 6000 Blackwell. Connect multiple GPUs with NVLink and choose reserved terms for predictable pricing.
- RTX PRO 6000 Blackwell
- NVLink multi-GPU
- Reserved terms
- CUDA images at boot
GPU pricing
Per-GPU hourly rates, with reserved terms for workloads that run continuously. Nodes include host CPU, RAM and local NVMe scratch sized to the card.
| GPU | Memory | On demand | 3-month | 12-month |
|---|---|---|---|---|
| NVIDIA RTX PRO 6000 Blackwell | 48 GB | 5.50 / hr | 4.50 / hr | 3.50 / hr |
Per-GPU pricing in AED, exclusive of 5% UAE VAT. Multi-GPU NVLink nodes are quoted per node. Capacity is allocated per project and confirmed at quotation.
NVIDIA RTX PRO 6000 Blackwell
The NVIDIA RTX PRO 6000 Blackwell delivers exceptional performance for AI training and inference, with 48 GB of memory to accommodate large models and batch sizes.
NVIDIA RTX PRO 6000 Blackwell
5.50 AED/hrPrices exclusive of 5% UAE VAT; reserved terms reduce the hourly rate.
Where UAE teams are using this
The pattern is consistent: the model is not the constraint, the data residency requirement is.
Arabic and bilingual models
Fine-tuning open-weight models on Arabic corpora that cannot be uploaded to a foreign region under the organisation's own policy.
Computer vision at scale
Training detection and classification models on camera and drone footage from UAE sites, then serving them at the edge.
Regulated-sector AI
Health, finance and government workloads where the residency requirement is a licence condition rather than a preference.
Forecasting and optimisation
Demand, energy and logistics models trained on operational data that sits in the same region as the GPUs.
Retrieval-augmented generation
Vector databases and embedding pipelines hosted alongside the inference endpoint, with documents never leaving the tenancy.
Production inference
Autoscaling inference on Kubernetes with GPU node pools, scaling on queue depth so idle cards do not accumulate cost.
Ready at boot, not after two
days of driver debugging.
Images ship with current CUDA, cuDNN and NCCL, plus the frameworks most teams start from. If you need a specific version pinned for reproducibility, we will build the image and keep it.
Node configuration guidance
Three ways teams use the GPU fleet
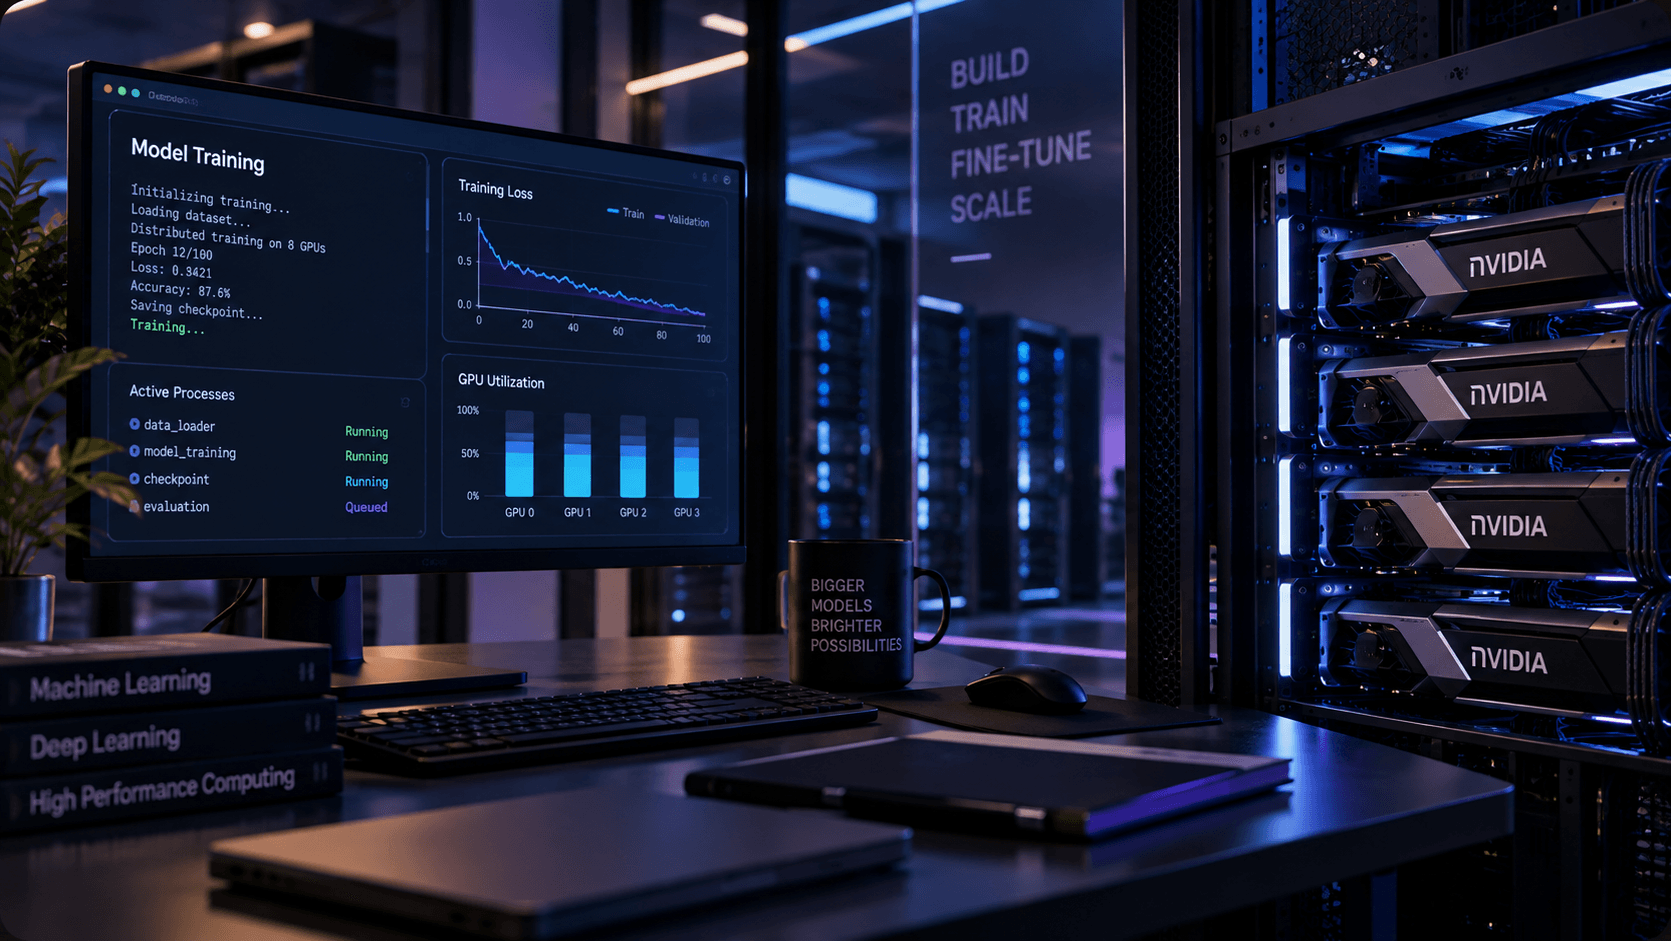
Fine-tune on multi-GPU nodes without fighting NCCL yourself
NVIDIA RTX PRO 6000 Blackwell nodes ship with NCCL pre-configured, so multi-GPU jobs scale close to linearly instead of bottlenecking on interconnect.
- Pre-built PyTorch, JAX and TensorFlow images
- Checkpointing to attached NVMe or object storage
- Reserved terms for multi-week training runs
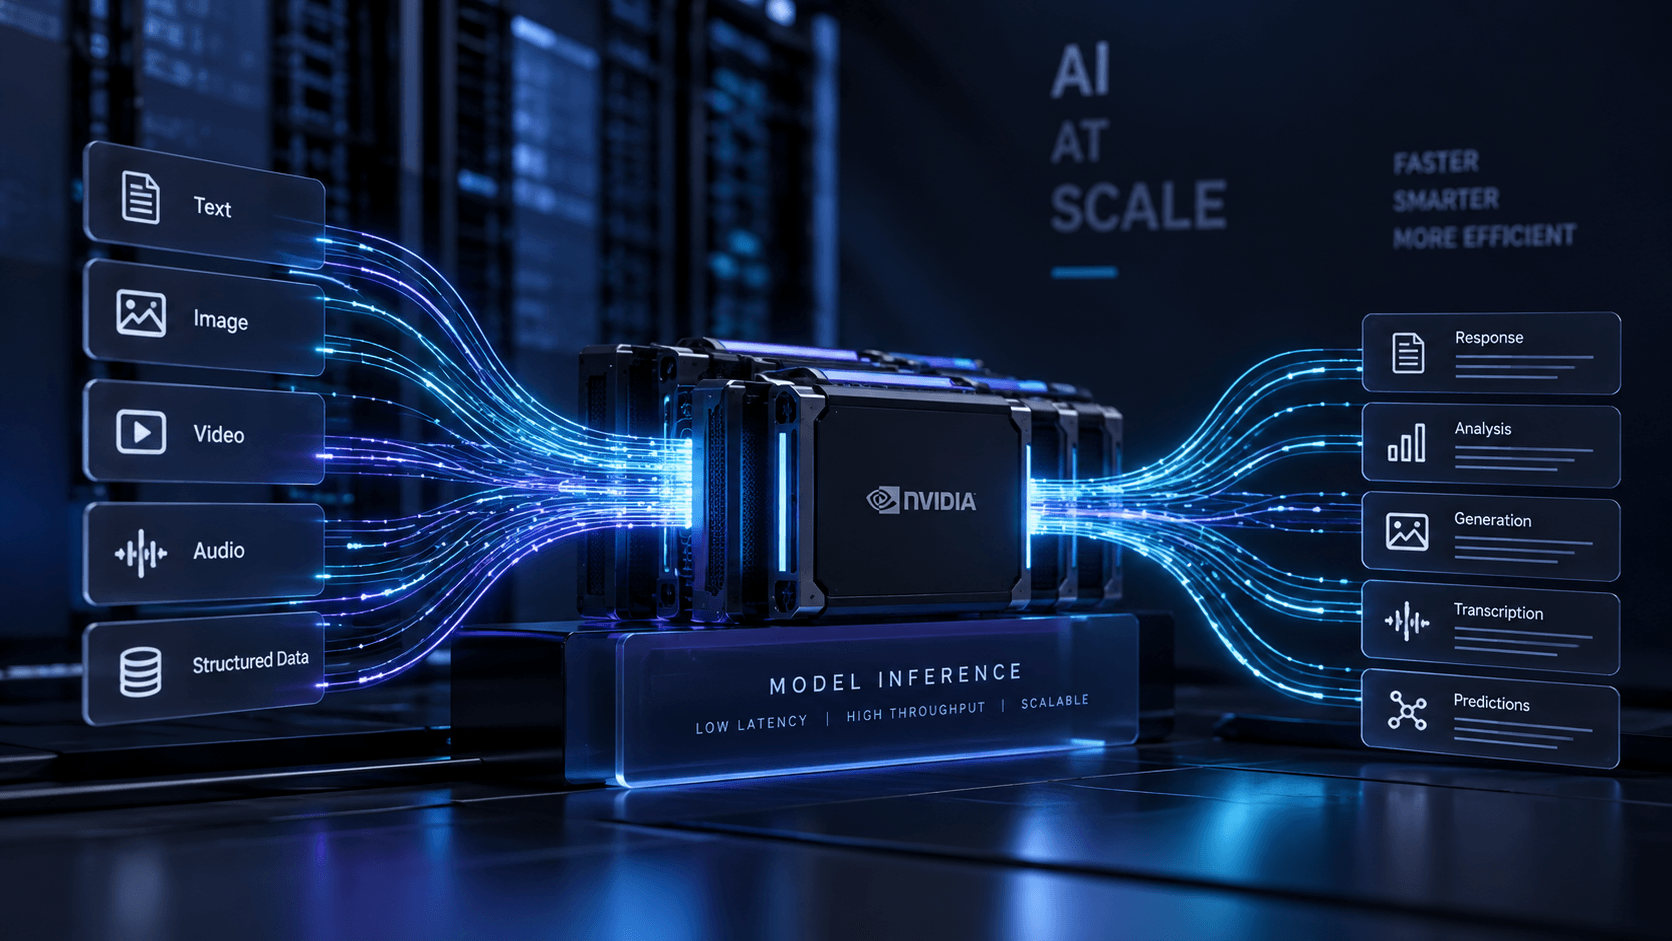
Serve models at a latency budget you actually chose
NVIDIA RTX PRO 6000 Blackwell pools handle high-throughput inference with exceptional cost efficiency, with vLLM and TensorRT-LLM images ready to deploy behind a load balancer.
- Autoscaling inference pools
- Per-request latency and throughput metrics
- Mix GPU tiers behind one endpoint by cost tier

Render, upscale and generate without a rendering farm to manage
Batch jobs for diffusion models, video upscaling and 3D rendering run on-demand GPU nodes that spin up for the job and disappear when it's done.
- Hourly billing suited to bursty batch workloads
- Shared object storage for input and output assets
- Job queue integration via API or Terraform
Frequently asked questions
NVIDIA RTX PRO 6000 Blackwell. Availability varies by configuration — single-GPU nodes are usually available within a business day, while multi-GPU nodes and large reservations are scheduled against confirmed capacity.
Not unless you move it. Compute, object storage and block volumes sit in the same UAE region, and the residency commitment is written into the Data Processing Agreement rather than implied by marketing copy.
Substantially. A twelve-month reservation is roughly a third below the on-demand rate. If your workload runs more than about eight hours a day on average, reserving is almost always the cheaper option.
We size infrastructure, build the training and inference pipeline, and operate it. We are an infrastructure partner rather than a research lab — if you need model research, we will say so rather than take the work.
The RTX PRO 6000 Blackwell is exceptionally well-suited for serving. We deploy inference on Kubernetes with autoscaling on queue depth, so the GPU count follows demand instead of sitting idle overnight.